Claude Hybrid Reasoning: A Practical Evaluation Framework
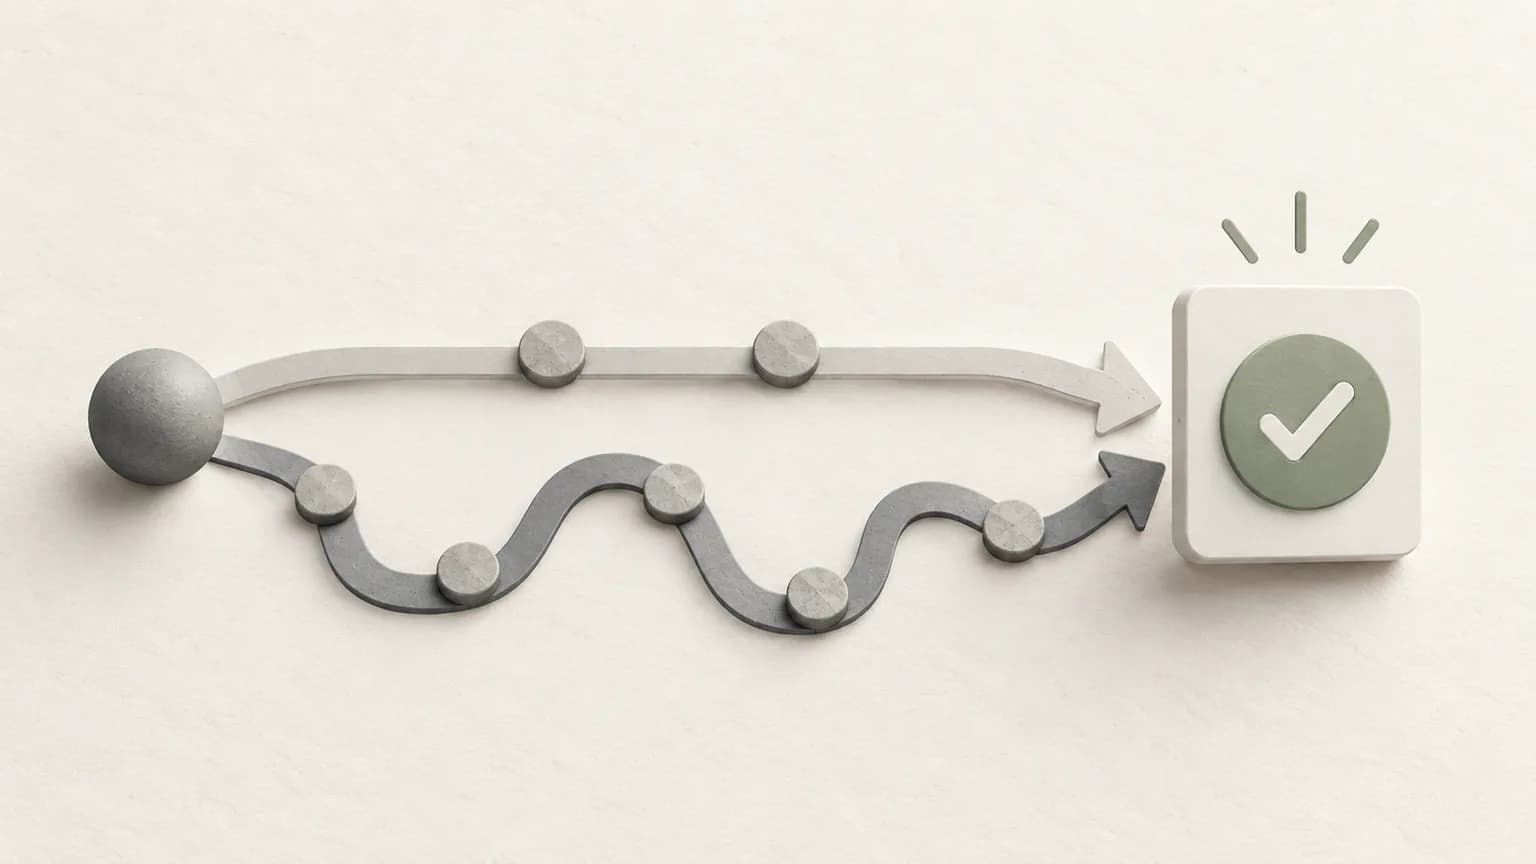
Compare fast and extended reasoning modes with the same tasks, evidence requirements, latency measures and review criteria.
Save and restore browser sessions, organize too many tabs, and keep useful notes beside your sources. Explore product updates and research workflows.

Compare fast and extended reasoning modes with the same tasks, evidence requirements, latency measures and review criteria.

Evaluate Midjourney V7 prompt adherence and visual consistency with controlled prompts, saved settings and honest selection criteria.

Test citation coverage, source quality, freshness and claim support before building a research workflow around an AI search API.

Assess on-device language models through model cards, hardware constraints, privacy boundaries and task-level measurements.

Review channel access, context boundaries, approval steps and auditability before introducing an AI agent into team conversations.

Evaluate an agent platform through retrieval quality, tool permissions, observability, deployment effort and failure recovery.